
Search engines use automated programs called crawlers or bots to discover and analyze websites. These crawlers help search engines understand website content and decide which pages should appear in search results.
The robots.txt file plays an important role in communicating with search engine crawlers. It provides instructions about which sections of a website can or cannot be accessed.
Proper robots.txt configuration is an important part of technical SEO because incorrect settings can prevent important pages from being discovered.
What is a Robots.txt File?
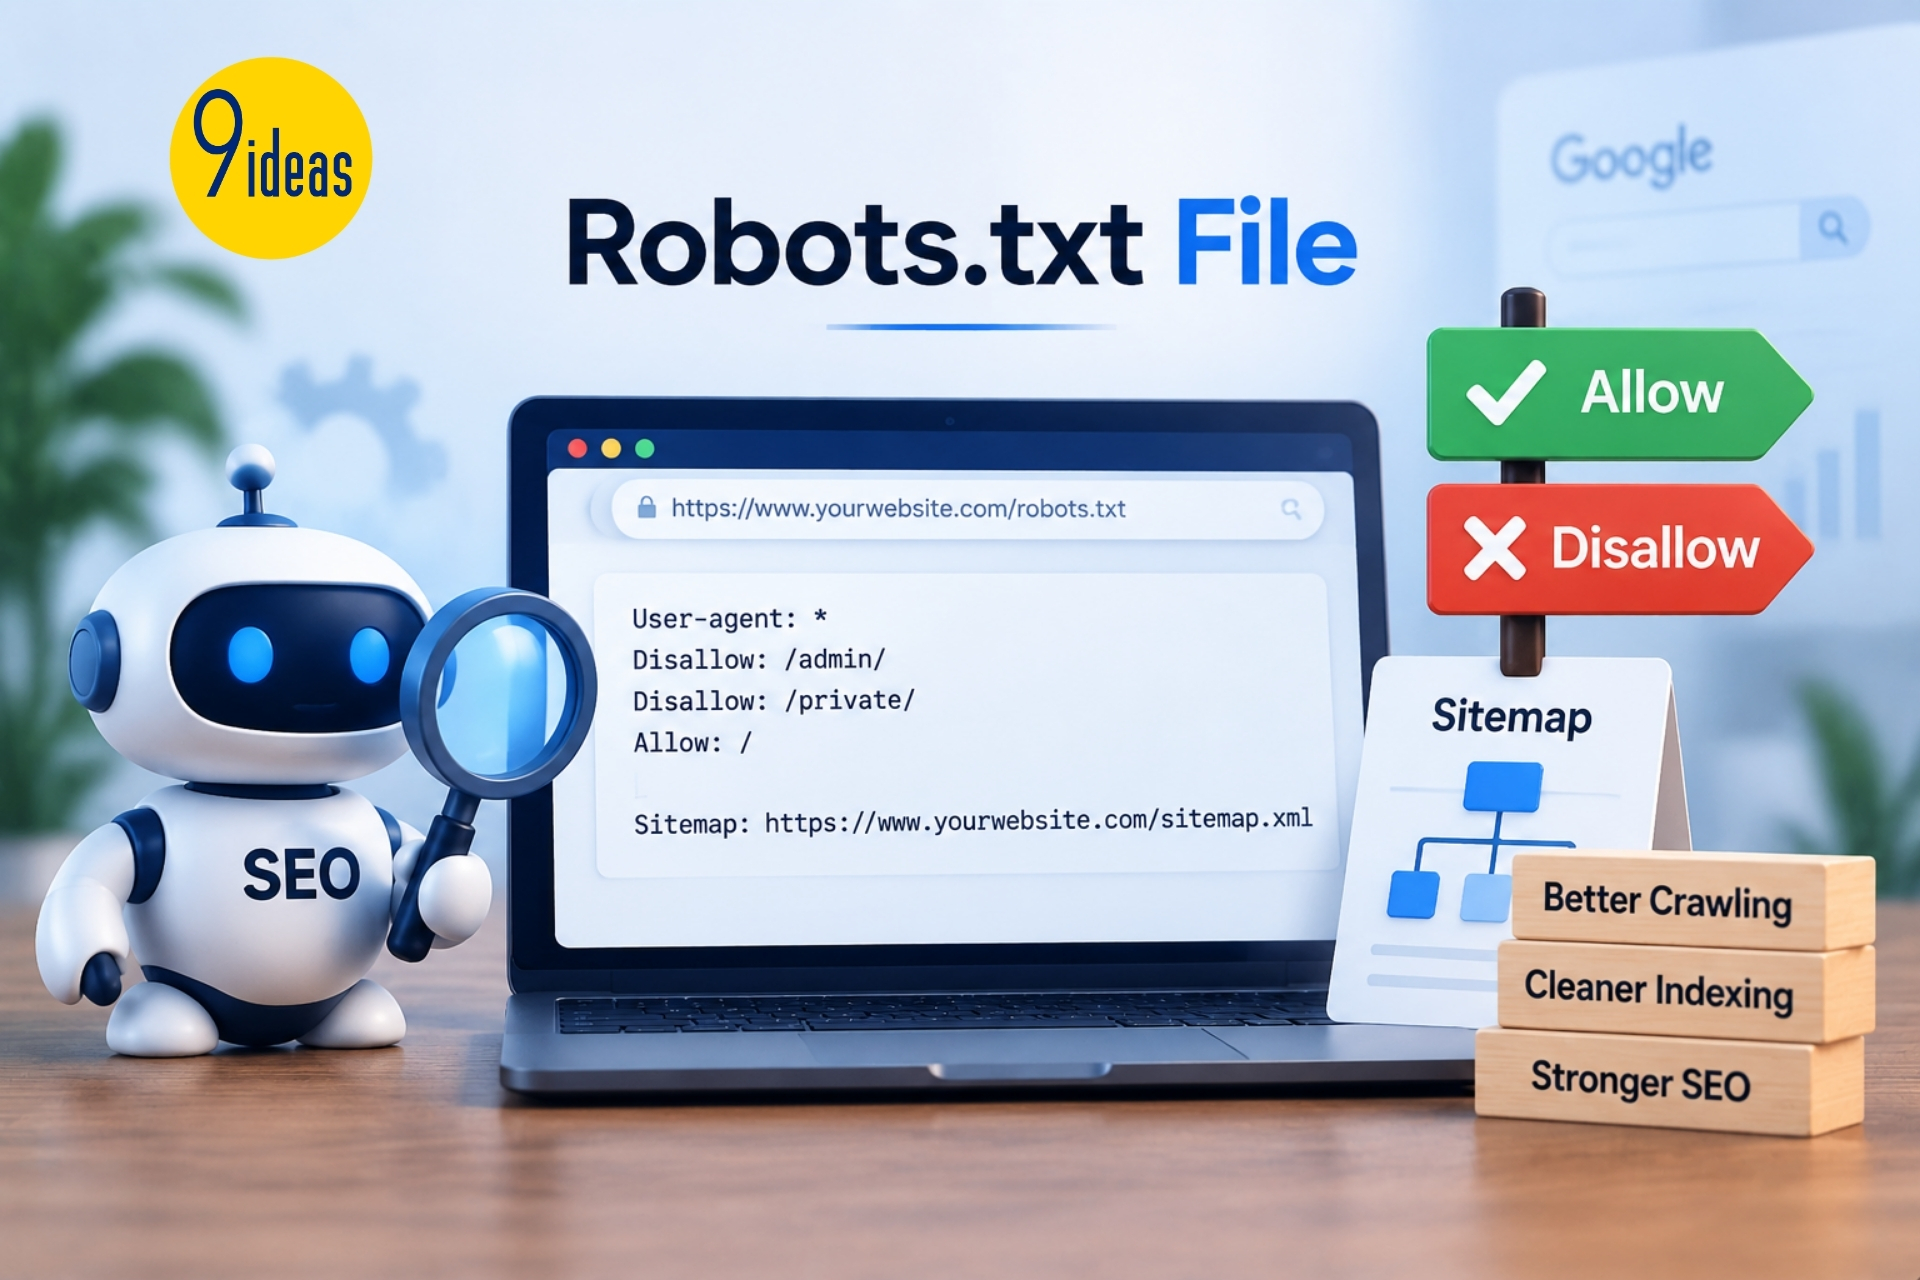
A robots.txt file is a simple text file placed in the root directory of a website that provides instructions to search engine bots.
It tells crawlers:
- Which pages they can access
- Which sections they should avoid
- Where the XML sitemap is located
The file is usually available at:
example.com/robots.txt
Why Robots.txt is Important for SEO
Controls Website Crawling
Search engines have limited resources when crawling websites.
Robots.txt helps guide crawlers toward important content while avoiding unnecessary sections.
Examples of pages that may not need crawling:
- Admin areas
- Internal search pages
- Temporary files
- Duplicate content sections
Improves Crawl Efficiency
Large websites may contain thousands of pages.
Proper robots.txt configuration helps search engines focus on valuable pages instead of wasting crawl resources on unnecessary URLs.
Protects Sensitive Website Areas
Robots.txt can prevent search engines from accessing certain areas of a website.
However, it should not be considered a security method because blocked URLs may still be discovered through other sources.
Common Robots.txt Directives
User-agent
Defines which crawler the rule applies to.
Example:
Googlebot
Bingbot
All search engines
Disallow
Blocks access to specific website sections.
Example uses:
- /admin/
- /private/
- /temporary/
Allow
Allows access to specific pages inside blocked sections.
Sitemap
Provides the location of the XML sitemap.
This helps search engines discover website structure.
Common Robots.txt Mistakes
Blocking Important Pages
Incorrect rules may prevent search engines from accessing important content.
Examples:
- Homepage blocked
- Service pages blocked
- Blog pages blocked
Using Robots.txt as Security
Robots.txt does not protect confidential information.
Sensitive data should be secured through proper authentication methods.
Incorrect Syntax
Small errors can affect crawler behaviour.
Regular testing is important to ensure correct configuration.
Robots.txt and Technical SEO
Robots.txt works together with other technical SEO elements:
Robots.txt → Crawling Instructions
XML Sitemap → Website Discovery
Internal Links → Page Relationships
Structured Data → Content Understanding
Together, these elements help search engines better understand websites.
How to Test Robots.txt
Website owners can review robots.txt using:
- Google Search Console
- SEO auditing tools
- Manual browser checks
Regular monitoring helps identify crawling problems.
Conclusion
The robots.txt file is an important technical SEO element that helps website owners guide search engine crawlers efficiently.
A properly configured robots.txt file improves crawl management, protects unnecessary pages from indexing and supports better website structure.
Frequently Asked Questions (FAQs)
1. What is a robots.txt file?
A robots.txt file provides instructions to search engine crawlers about which website pages they can access.
2. Does robots.txt improve SEO rankings?
Robots.txt does not directly improve rankings but helps search engines crawl websites efficiently.
3. Can robots.txt block Google from indexing pages?
Yes, incorrect robots.txt rules can prevent Google from accessing important pages.
4. Is robots.txt required for every website?
Small websites may not always need custom robots.txt rules, but having a properly configured file is recommended.
5. Where is robots.txt located?
Robots.txt is placed in the root directory of a website.
